 About Urh Social
 Terms of Service
 Privacy Policy
 Contact
When your favourite API client stops being enough
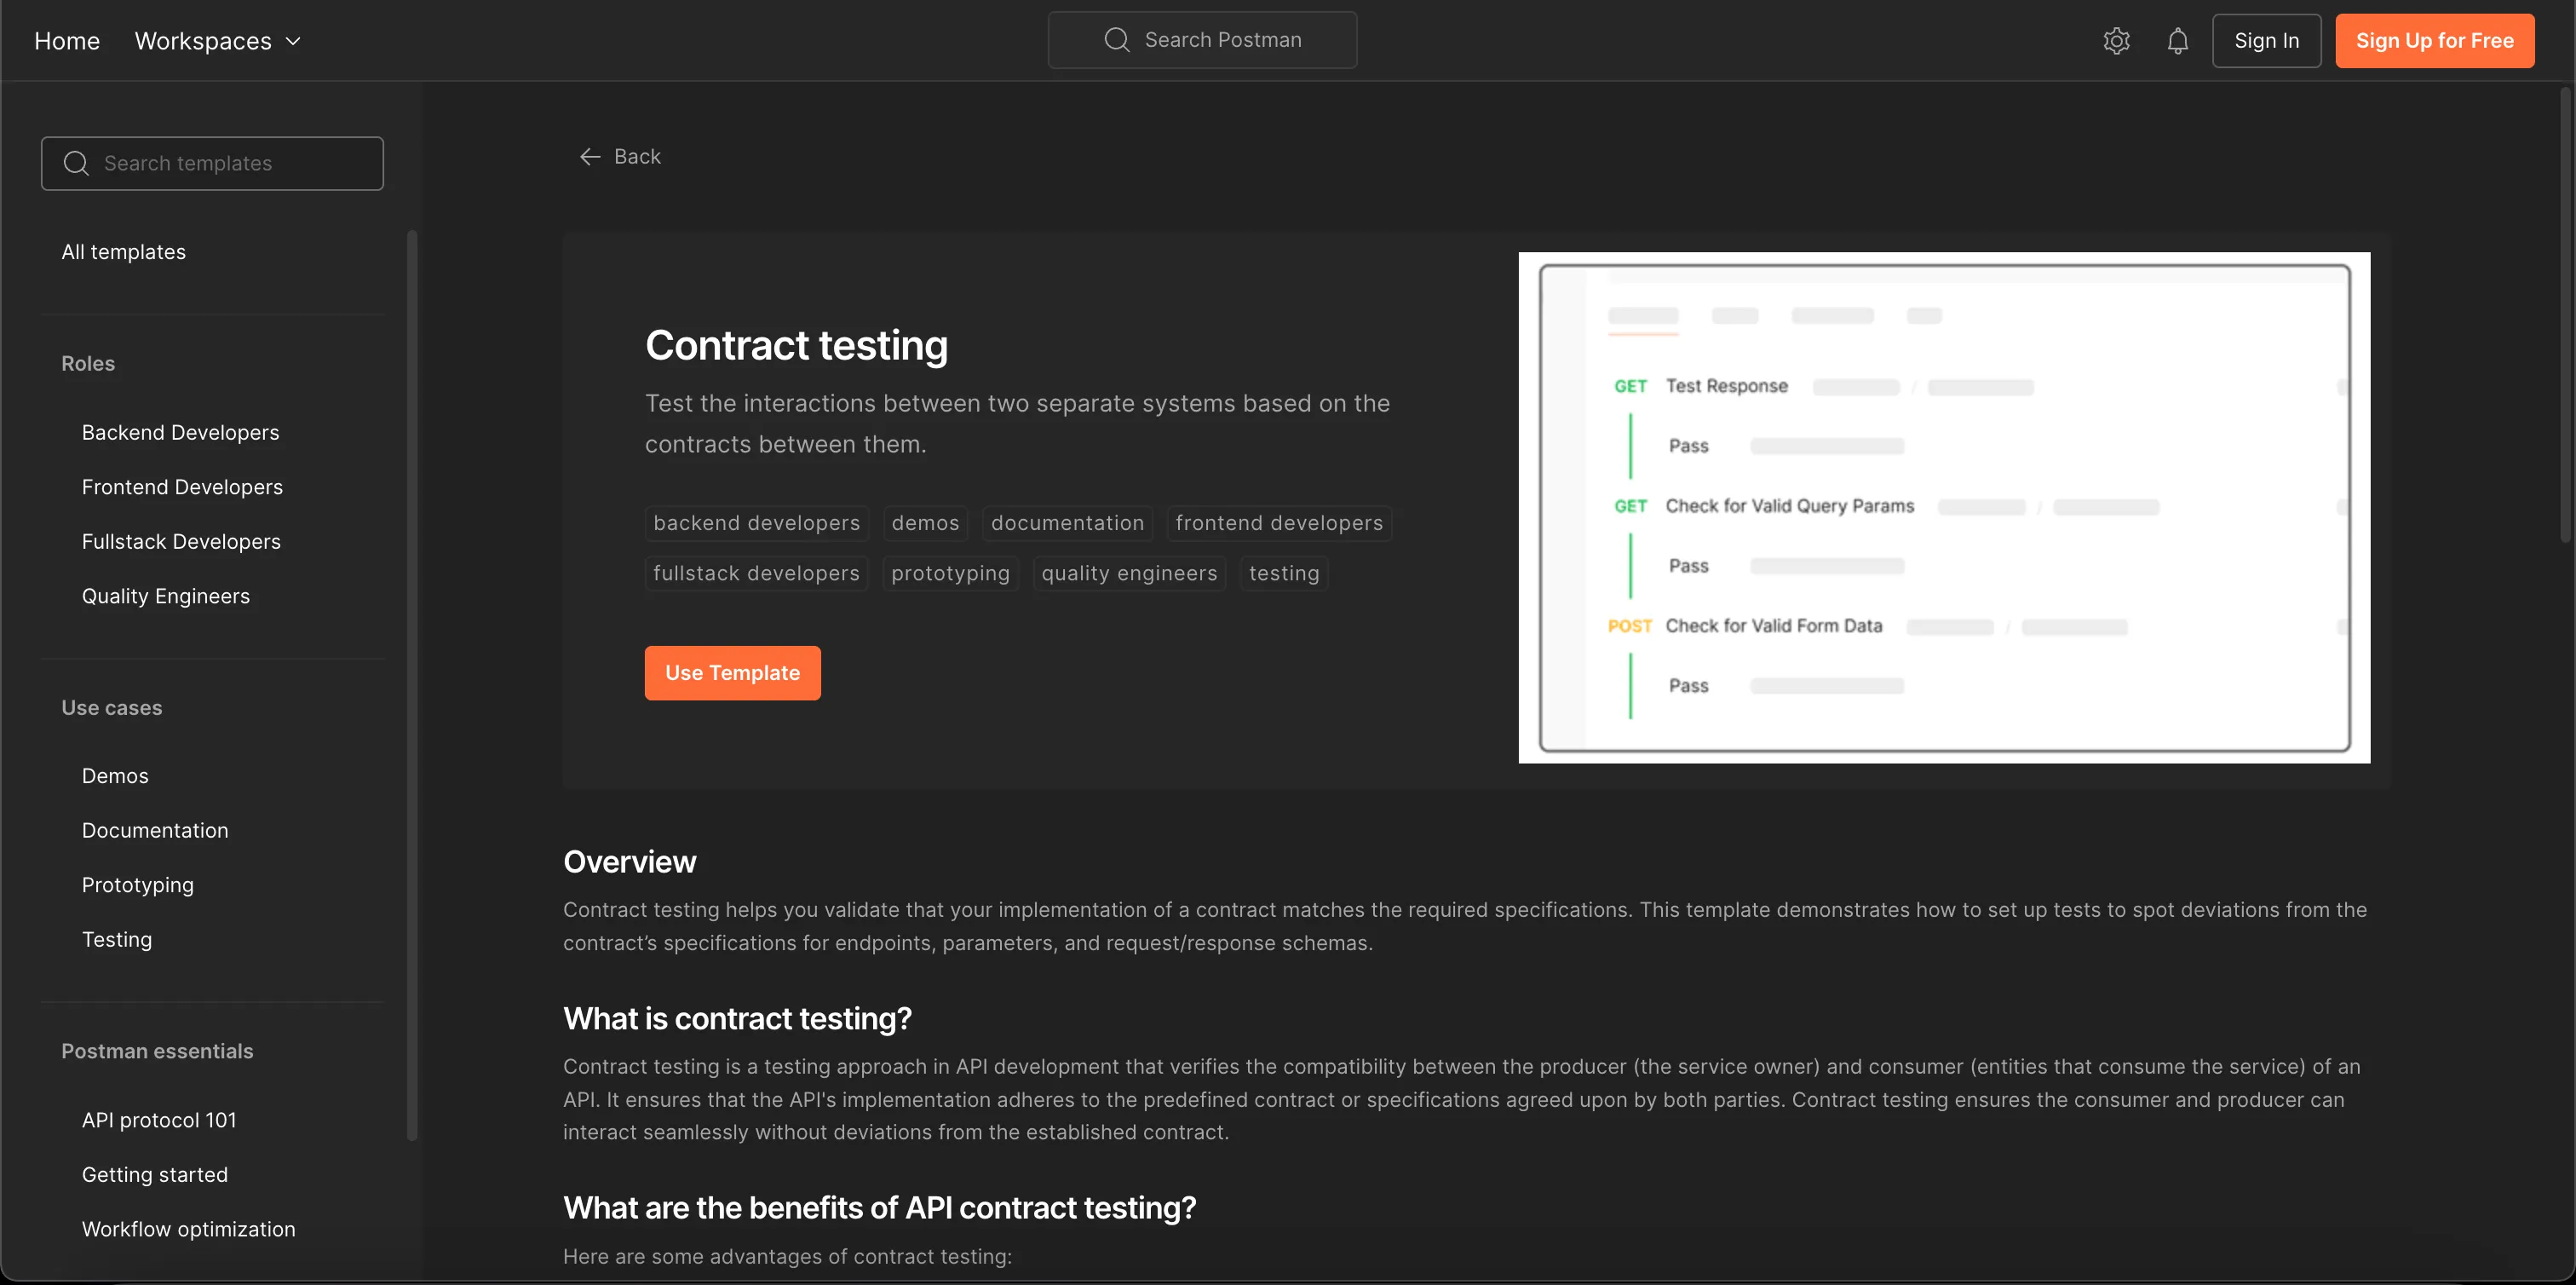
Almost every developer I know has a soft spot for their API client. It's usually the first tool you open when you join a new team. You import a collection, hit send, and within five minutes you understand more about the system than any architecture diagram could tell you.
I still use one most days. But over the years I've noticed a pattern. The tool that's perfect for exploring an API is often not the tool that's best for testing it at scale. At some point, a lot of teams start looking at other api testing tools like postman, not because the client is bad, but because their needs have changed.
Here's what that shift usually looks like, and what I'd think about if you're going through it.
It starts with a collection that nobody owns
On most teams, the shared collection begins life as a helpful little set of requests. Someone adds the login call, someone else adds the orders endpoints, and pretty soon you've got a few hundred requests spread across a dozen folders.
The trouble is that collections drift. Endpoints get renamed, payloads change, environments get added. Unless someone is actively maintaining it, the collection slowly turns into a museum of how the API used to work. I once spent half a morning debugging a "broken" endpoint before realising the request in our collection was two versions out of date.
Then someone tries to run it in CI
The next step is usually a well-meaning attempt to turn the collection into an automated test suite. You add some assertions, wire it into the pipeline with a command line runner, and for a while it works.
Then the cracks show. Tests depend on each other because they share variables set by earlier requests. One failure early in the run causes ten more further down. A staging service goes down for maintenance and the whole suite goes red. People start rerunning the pipeline until it passes, and the tests stop meaning much.
None of this is really the client's fault. It was built first and foremost for sending requests and exploring APIs. Using it as the backbone of a large automated test suite stretches it in directions it wasn't designed for.
Writing every test by hand gets old fast
The other pain point is effort. In a collection-based setup, every test is something a person has to sit down and write. You pick the request, craft the payload, write the assertions, and then remember to update all of it when the API changes.
That's fine for twenty endpoints. It's exhausting for two hundred. Coverage ends up reflecting how much time the team had, not how much risk the API actually carries.
This is where some newer approaches have genuinely changed things for me. A few tools can generate tests from an OpenAPI spec, and others can record real traffic from a running service and turn it into test cases with the dependencies mocked automatically. The first time I tried the traffic-based approach, it picked up edge cases our hand-written tests had missed for months.
Dependencies are the real headache
If I had to name the single biggest reason teams outgrow a simple API client for testing, it would be dependencies.
Modern services rarely stand alone. A single request might touch a database, a message queue, another team's service, and a third party provider. When your tests hit all of those for real, they're slow and unpredictable. The fix is mocking, and how easily a tool handles mocking says a lot about how well it will cope as your system grows.
What I'd look for in the next tool
If you're starting to feel these pains, here's roughly how I'd judge the alternatives.
First, can tests run independently? Each test should be able to pass or fail on its own, without relying on the one before it.
Second, how much of the test writing can it take off your hands? Generating tests from specs or real traffic saves an enormous amount of time compared to writing everything manually.
Third, how does it handle the services you don't control? Built-in mocking that stays in sync with reality is worth a lot.
Fourth, does it fit naturally into your pipeline? It should run from the command line, give clear exit codes, and produce failure messages that a developer can understand without opening a log file.
And finally, how painful is it to update tests when the API changes on purpose? This is the cost you'll pay every sprint, so it's worth checking during any trial.
You probably don't have to choose just one
Here's the part people often miss. Moving to a different testing tool doesn't mean throwing away the client you like. On most of the teams I've worked with, the two live side by side quite happily.
Developers still reach for their client to poke at an endpoint, debug a strange response, or share a quick example with a colleague. The automated suite, built with a tool designed for the job, runs on every pull request and catches regressions before they reach production. Each tool does what it's good at.
Making the switch without the drama
If you decide it's time to move your automated tests elsewhere, don't try to migrate everything in one go. Pick one service, ideally one that changes often and has a history of bugs, and build a proper suite for it with the new tool. Run it alongside your existing checks for a couple of weeks and see which one catches more.
In my experience, the results speak for themselves fairly quickly. Once the team sees fewer flaky runs and faster feedback on their pull requests, the rest of the migration tends to sell itself.

 English
 Arabic
 French
 Spanish
 Portuguese
 Deutsch
 Dutch
 Italiano
 Russian
 Romaian
 Portuguese (Brazil)
 Greek